Notes from the pipeline
What I learned building data pipelines, scrapers, and quantitative models — the numbers, the failure modes, and the things that broke quietly.

Data Ingestion Bugs and How to Catch Them
Five ways ingestion breaks, with the guard for each. Eight of about 30 bugs threw no error at all.
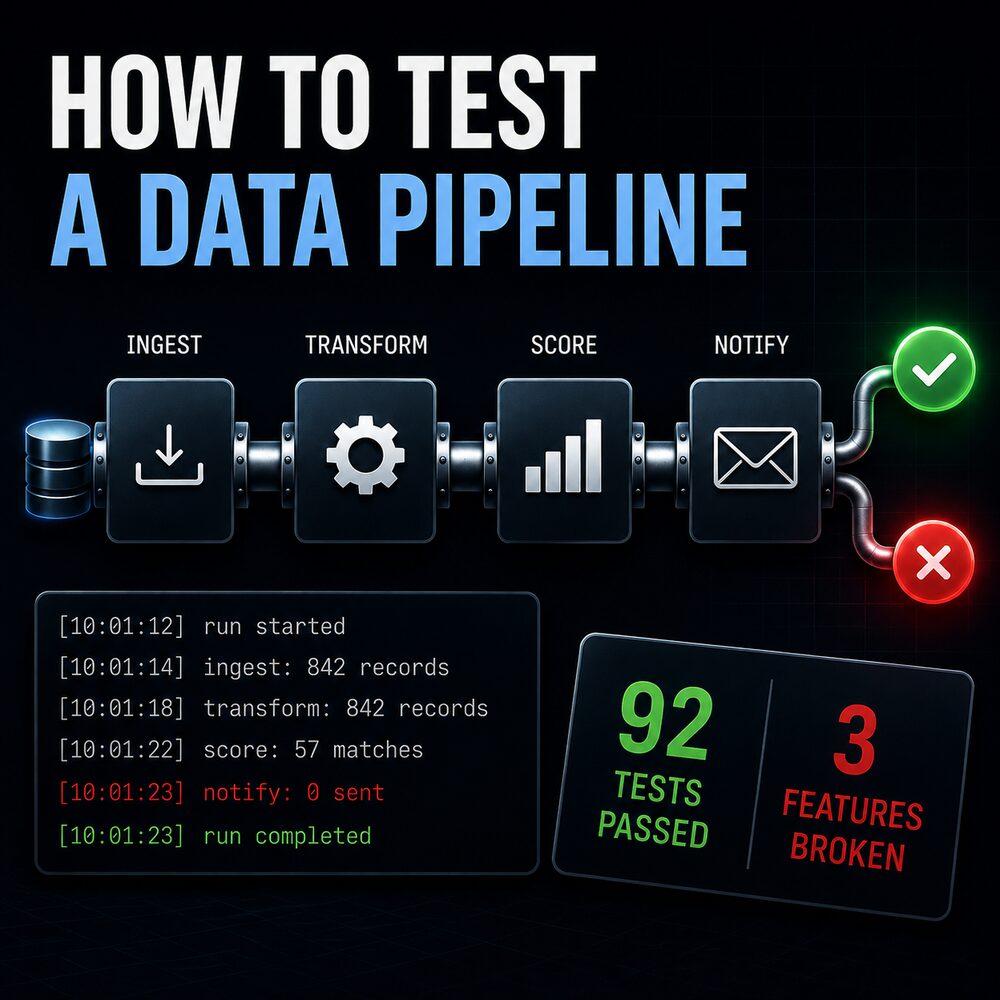
How to Test a Data Pipeline: What Tests Miss
A green suite is evidence about your code, not your data. The cheap tests that catch what it misses.
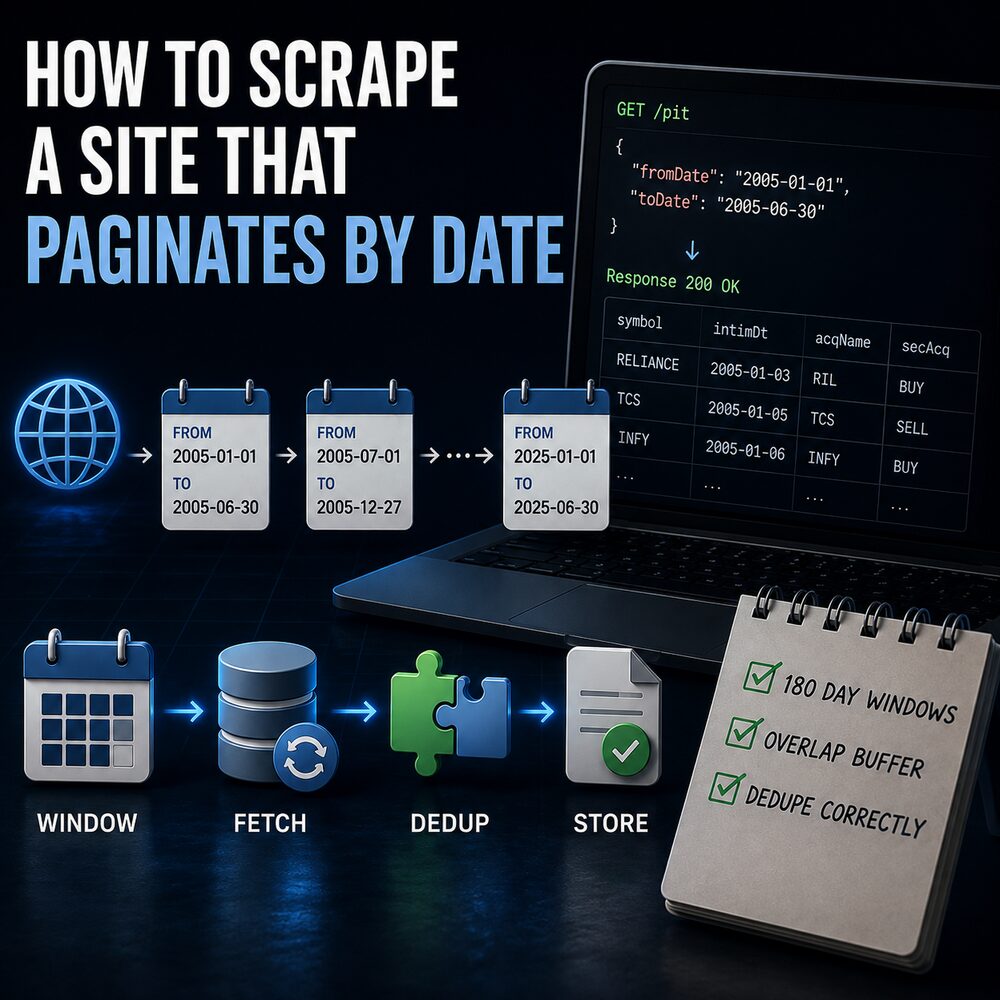
How to Scrape a Site That Paginates by Date
Find the undocumented window cap, resume from behind, and dedup on a key that cannot fail silently.
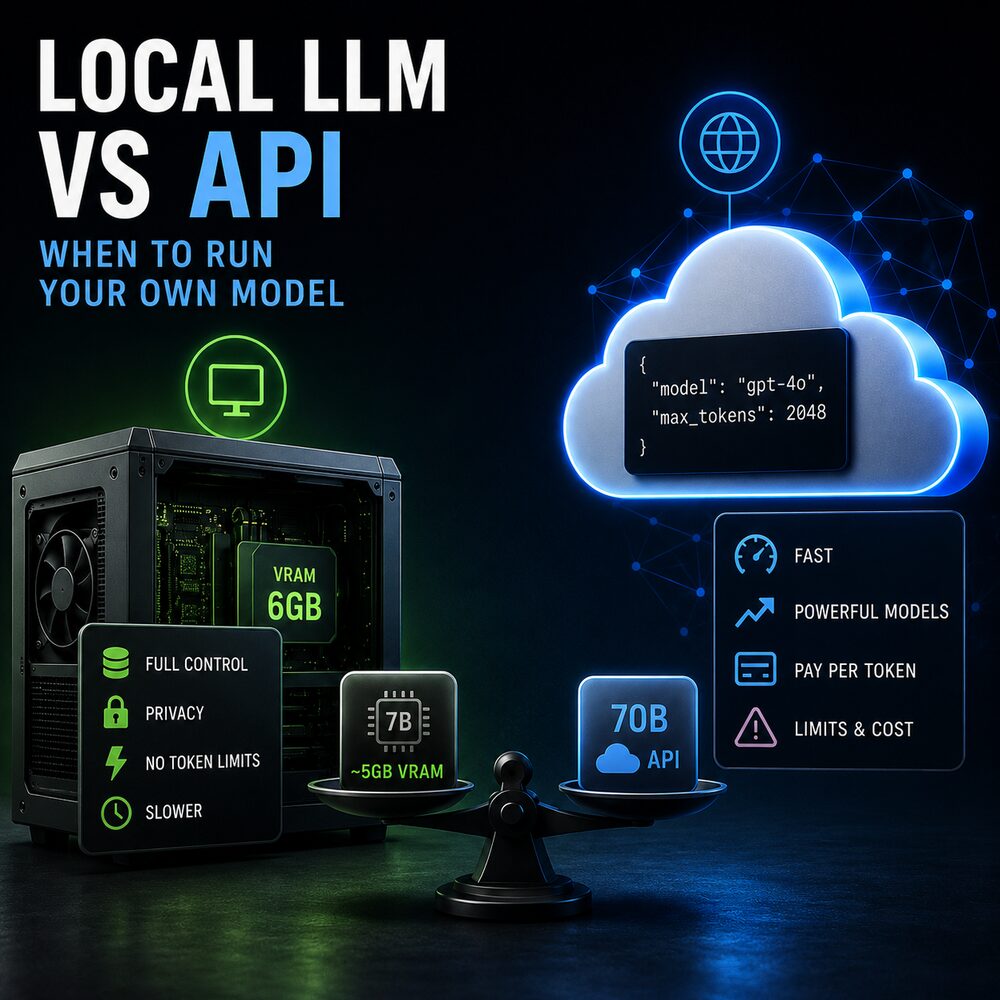
Local LLM vs API: When to Run Your Own Model
What fits in 6GB, what it costs in latency, and the schema trick that makes a small model usable.
How to Make an ETL Pipeline Safe to Rerun
A rerun should repair data, not corrupt it. Four ways that rule breaks, and a six-point checklist.
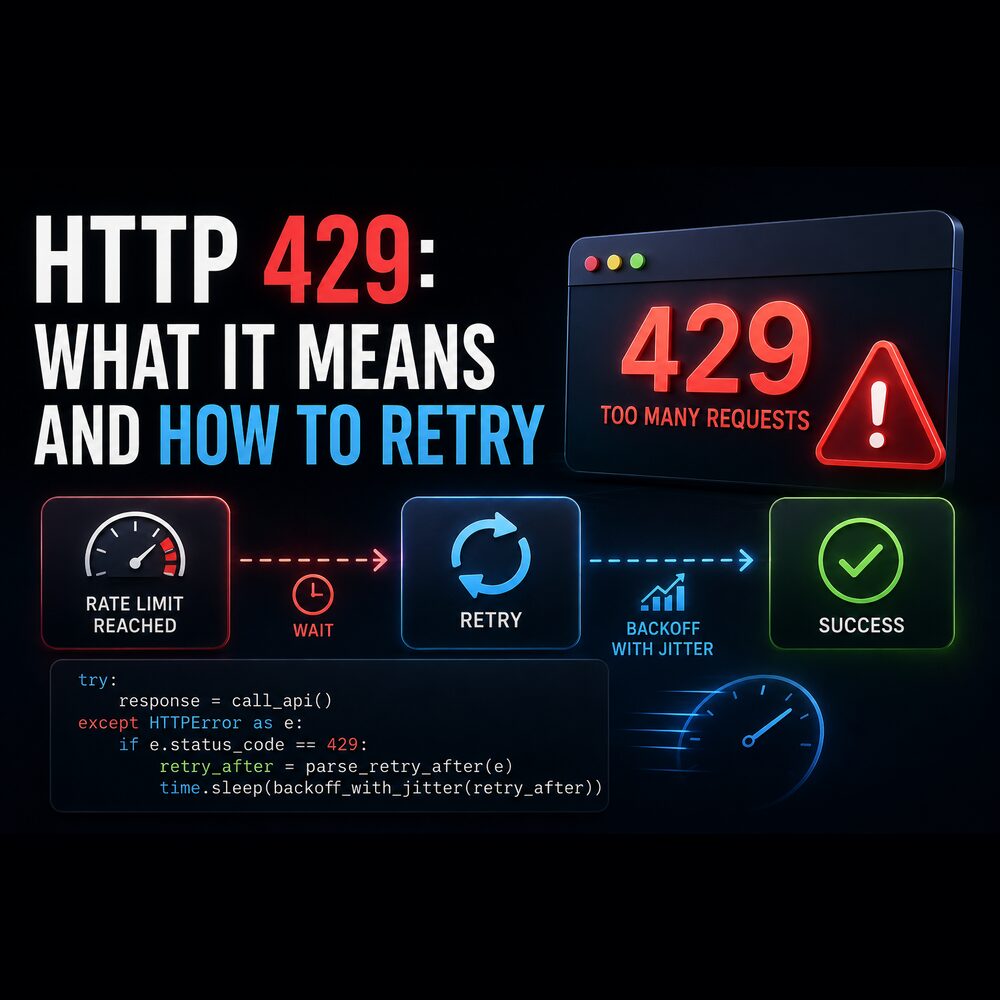
HTTP 429: What It Means and How to Retry
One status code, three meanings — wait, stop, or out of quota. How to tell them apart in code.
Can You Predict Stock Prices Minute by Minute?
Four checks that decide whether a short-horizon model has an edge. One real attempt failed all four.
Why Your Scraper Gets Blocked and How to Fix It
Four layers block you: headers, TLS fingerprint, IP, behaviour. How to tell which one, and the fix for each.
Playwright vs Selenium: Which to Use and When
Locators, saved sessions and pinned browsers — plus the 52 fixed sleeps that show what auto-waiting does not fix.