
01
Anti-Bot
Vishnujan NarayananData pipelines,from crawlers to APIs
I build the crawlers and scheduled jobs that pull data in, the tests that ensure the data is valid, and the APIs and apps that serve it.
scroll to see how I work
02
Resilient
Resilient
ETL & ML
Writing
Blogs
Notes from the build — deep dives on data pipelines, applied ML, and the engineering behind shipping systems that hold up in production.
How to Test a Data Pipeline: What Tests Miss
A green suite is evidence about your code, not your data. The cheap tests that catch what it misses.
Data Ingestion Bugs and How to Catch Them
Five ways ingestion breaks, with the guard for each. Eight of about 30 bugs threw no error at all.
How to Scrape a Site That Paginates by Date
Find the undocumented window cap, resume from behind, and dedup on a key that cannot fail silently.
Local LLM vs API: When to Run Your Own Model
What fits in 6GB, what it costs in latency, and the schema trick that makes a small model usable.
How to Make an ETL Pipeline Safe to Rerun
A rerun should repair data, not corrupt it. Four ways that rule breaks, and a six-point checklist.
HTTP 429: What It Means and How to Retry
One status code, three meanings — wait, stop, or out of quota. How to tell them apart in code.
Can You Predict Stock Prices Minute by Minute?
Four checks that decide whether a short-horizon model has an edge. One real attempt failed all four.
Why Your Scraper Gets Blocked and How to Fix It
Four layers block you: headers, TLS fingerprint, IP, behaviour. How to tell which one, and the fix for each.
Playwright vs Selenium: Which to Use and When
Locators, saved sessions and pinned browsers — plus the 52 fixed sleeps that show what auto-waiting does not fix.
 28-pipeline NSE market-data ingestion layer feeding 12+ datasets into a partitioned store.Market Data Platform
Full-stack TypeScript app scraping a book catalog into PostgreSQL, served via Next.js with real-time WebSocket scraping.Product ExplorerView demo
Solo-built production legal-emergency platform — ~30 Express endpoints over PostgreSQL with JWT auth, a real-time Twilio call-dispatch engine, and Haversine lawyer matching, deployed on Railway and Vercel.DekhLaw Legal-Emergency PlatformView demo
Production law-firm marketing site in Next.js 14 + TypeScript — 14 routes, Resend-backed lead capture, Zod-validated forms, and full SEO/JSON-LD, designed and shipped solo.Law Firm WebsiteView demo
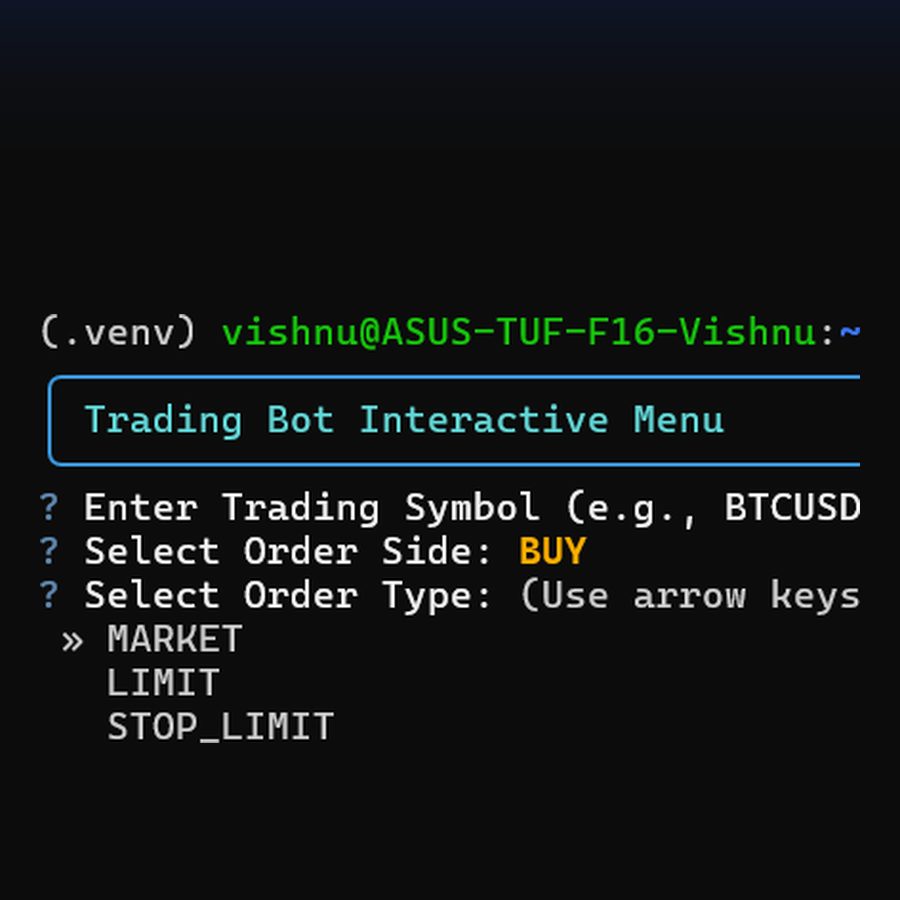
Autonomous job-search bot — scrapes Indeed, Glassdoor, and LinkedIn listings, scores them against a master profile, and builds a tailored resume per match with an LLM, rendered on demand via FastAPI.Job Application BotView code
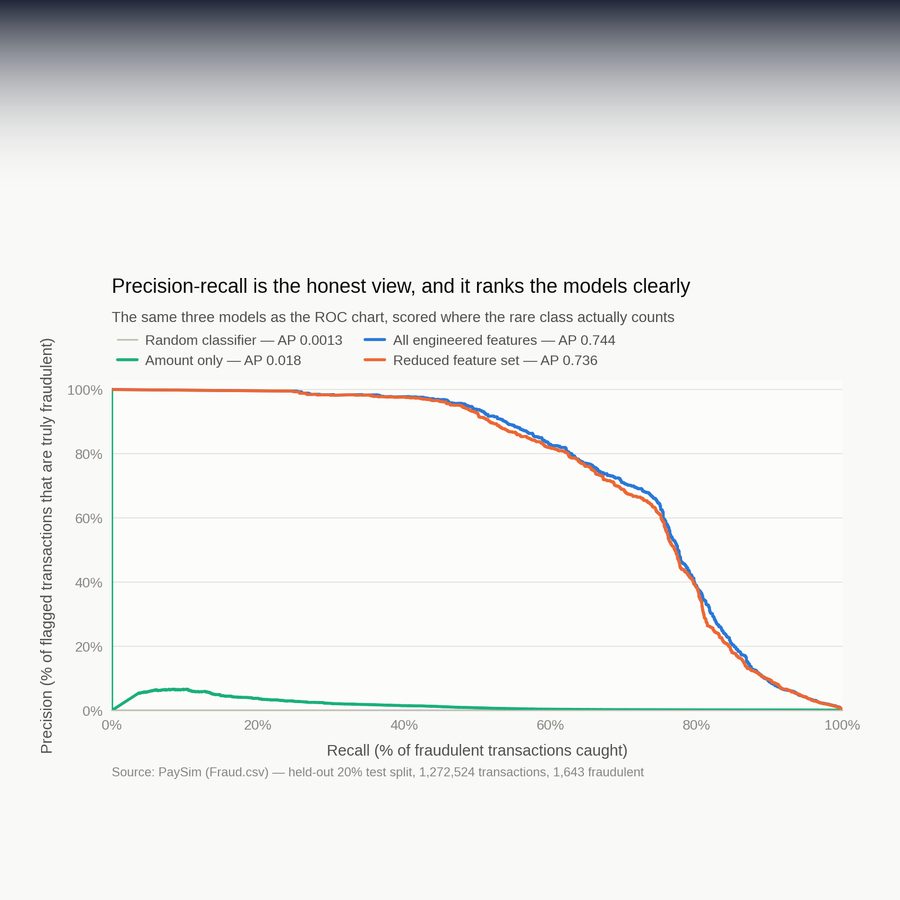 Fraud-detection model on 6.4M transactions — 95% caught at 0.995 ROC-AUC despite a 0.13% fraud rate.Fraud Transaction DetectionView demo
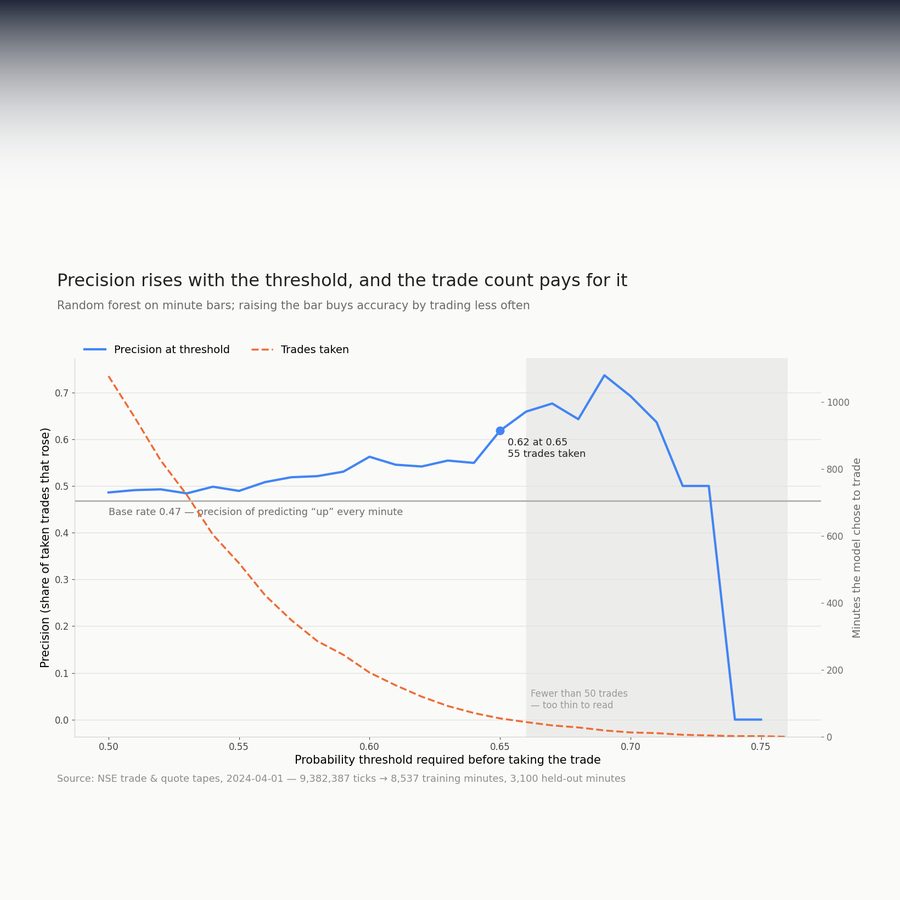 Intraday price-direction system over 9.4M NSE ticks, raising next-minute precision from 0.51 to 0.61.Minute-Level Stock PredictionView code
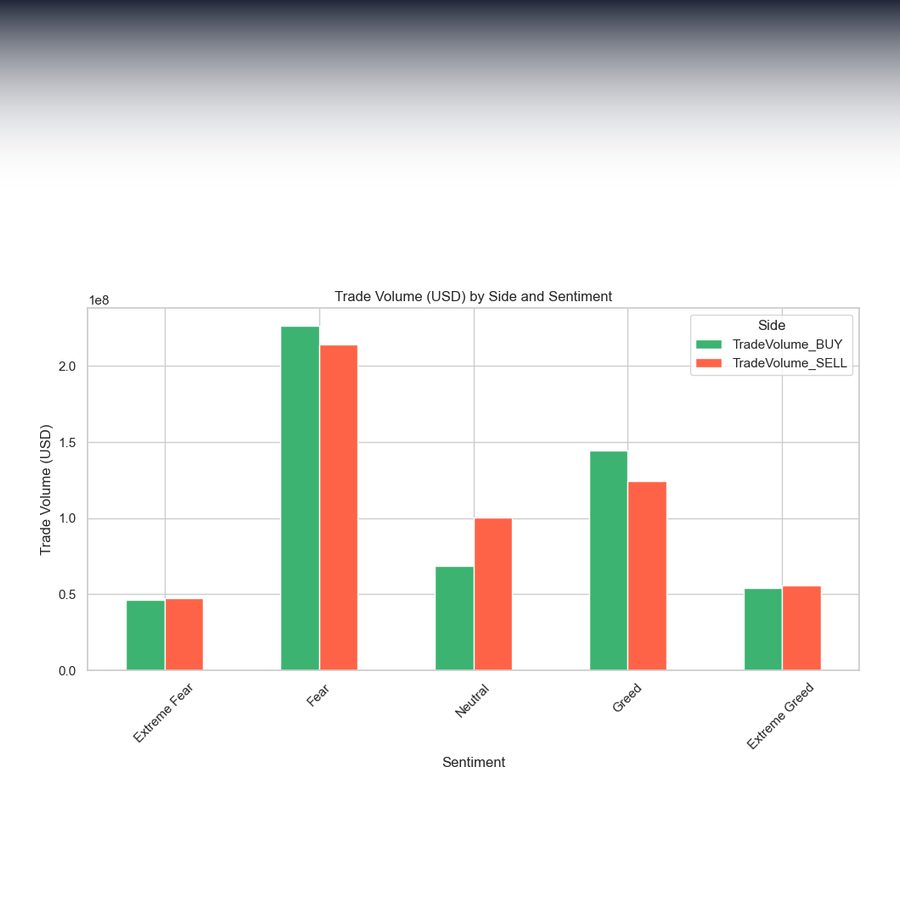 Quantified how Bitcoin Fear & Greed sentiment drives trader PnL across 211K crypto trades, with a contrarian sentiment-gated signal.Trader Sentiment AnalysisView demo
NLP pipeline for support tickets — issue-type classification and rule-based entity extraction, served via a Gradio app. Urgency scored at chance and is reported, not claimed.Support Ticket ClassifierView demo
Semantic quote search — fine-tuned sentence embeddings + FAISS index over ~2,500 quotes, served through Streamlit.Semantic Quote RetrievalView demo
Multi-task CNN predicting age and gender from a face photo, trained on 10,000+ UTKFace images with face detection and alignment.Age & Gender ClassifierView demo
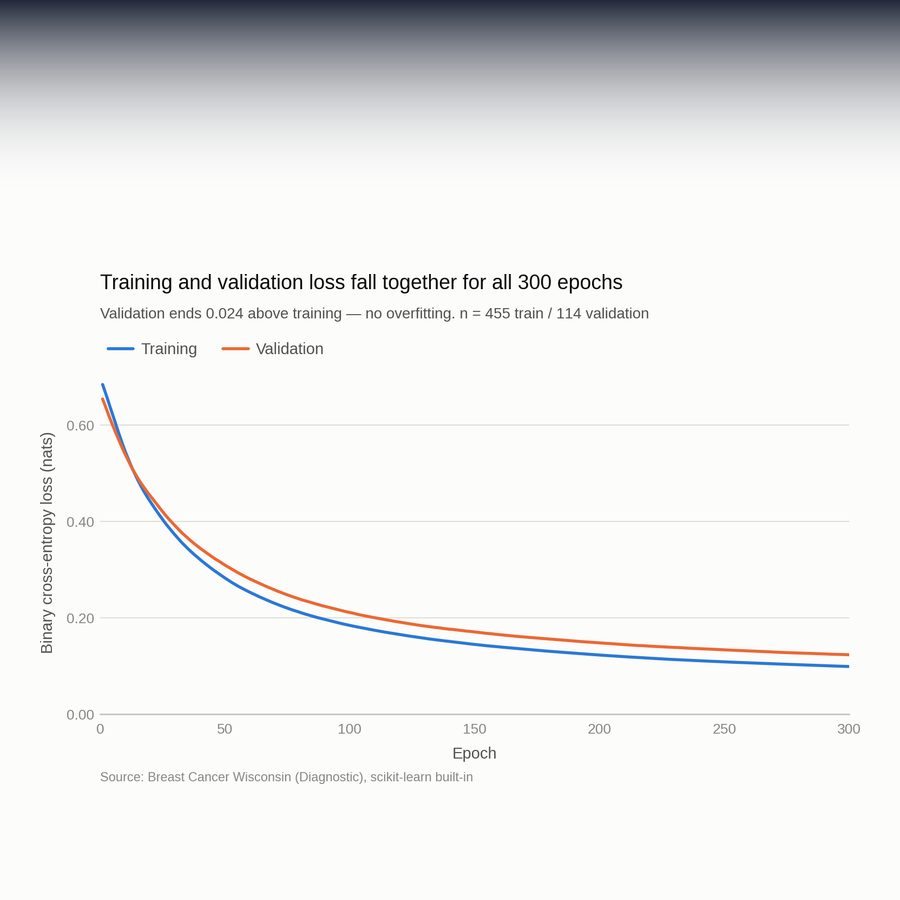 Feed-forward classifier built in pure NumPy — 97.4% accuracy / 0.995 ROC-AUC on Breast-Cancer-Wisconsin, with hand-derived backprop.Neural Network From ScratchView demo
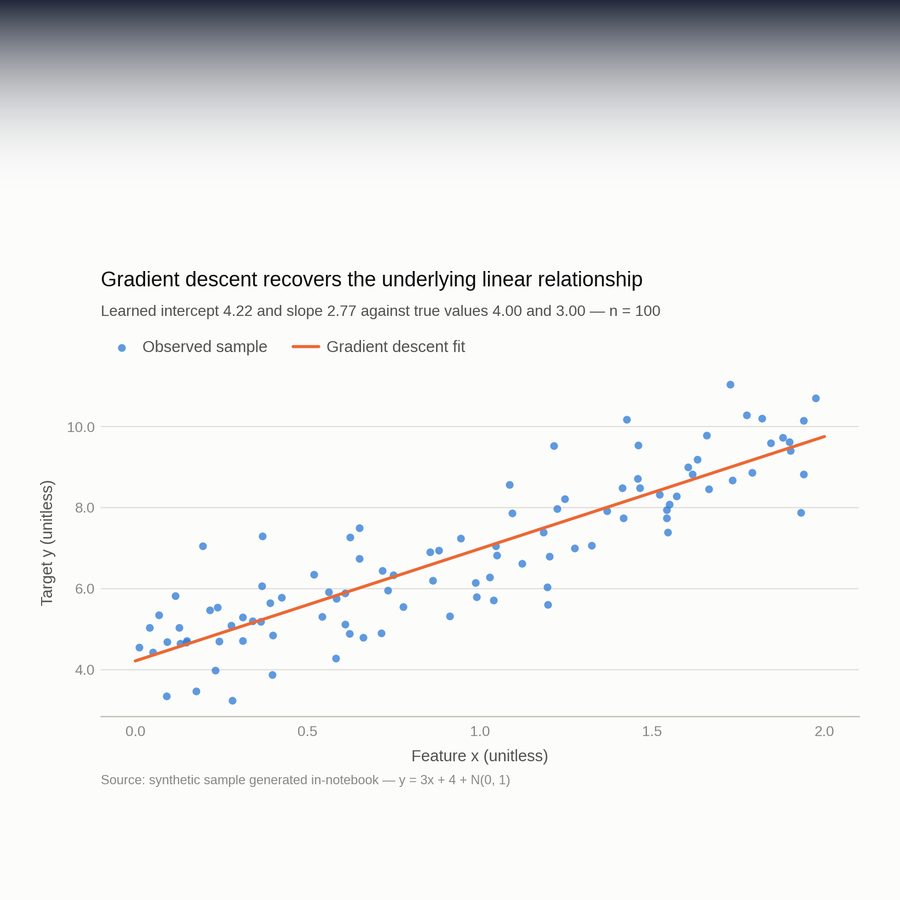 Linear regression built end to end in pure NumPy — hand-derived gradient descent and a closed-form solver, validated vs scikit-learn.Linear Regression From ScratchView code


No callbacks?
Your resume isn’t talking their language.
Recruiters get 200+ per role. Generic gets filtered before a human looks. Your experience isn’t the problem.
The fix
The bot reads the JD and selects the exact bullets, title and skill framing that match it. Every application speaks that role’s specific language. Automatically. Every time.
Applicant #847.
Window closed 3 hours ago.
Recruiters stop reading after the first 50. The window is under an hour from posting. You can’t watch three boards while that window opens and shuts.
The fix
The bot monitors Indeed, Glassdoor and LinkedIn continuously. The moment a match posts, you get a Telegram ping with the apply link and a tailored résumé ready to go. First wave, not after it.
Tweaking the same
résumé. Again.
10 roles a day is 10 tailoring sessions. You’re spending more time in Word than applying. And the rushed ones always look it.
The fix
You write your bullets once. The bot selects the right ones per role, every time. Your master profile becomes every tailored résumé you’ll ever need.
In development · Lab 01
Coming soon
PythonFastAPIPostgres + pgvectorPlaywrightTelegram
Check Out My Socials
Write-ups on data engineering — ingestion, validation, and the services on top.
FollowVishnu · Ex-chinmayite · UPES’25
Follow ↗Data Engineer | From crawlers to APIs
Ernakulam, Kerala, India 500+ connections ConnectData pipelines, from crawlers to APIs. Ingestion, data validity, and the services on top.
- Fraud_Transaction_Detection
- minute-level-stock-prediction
- Trader_sentiment_analysis
View profile ↗Notes from the build — data pipelines, scraping, and the reliability work in between.
Subscribe ↗Build logs and walkthroughs — pipelines, scraping, and the tooling around them.
SubscribeHi Vishnujan — I saw your work and wanted to ask about
Follow me on social media