How to scrape a site that paginates by date

Find the undocumented window cap, resume from behind, and dedup on a key that cannot fail silently.
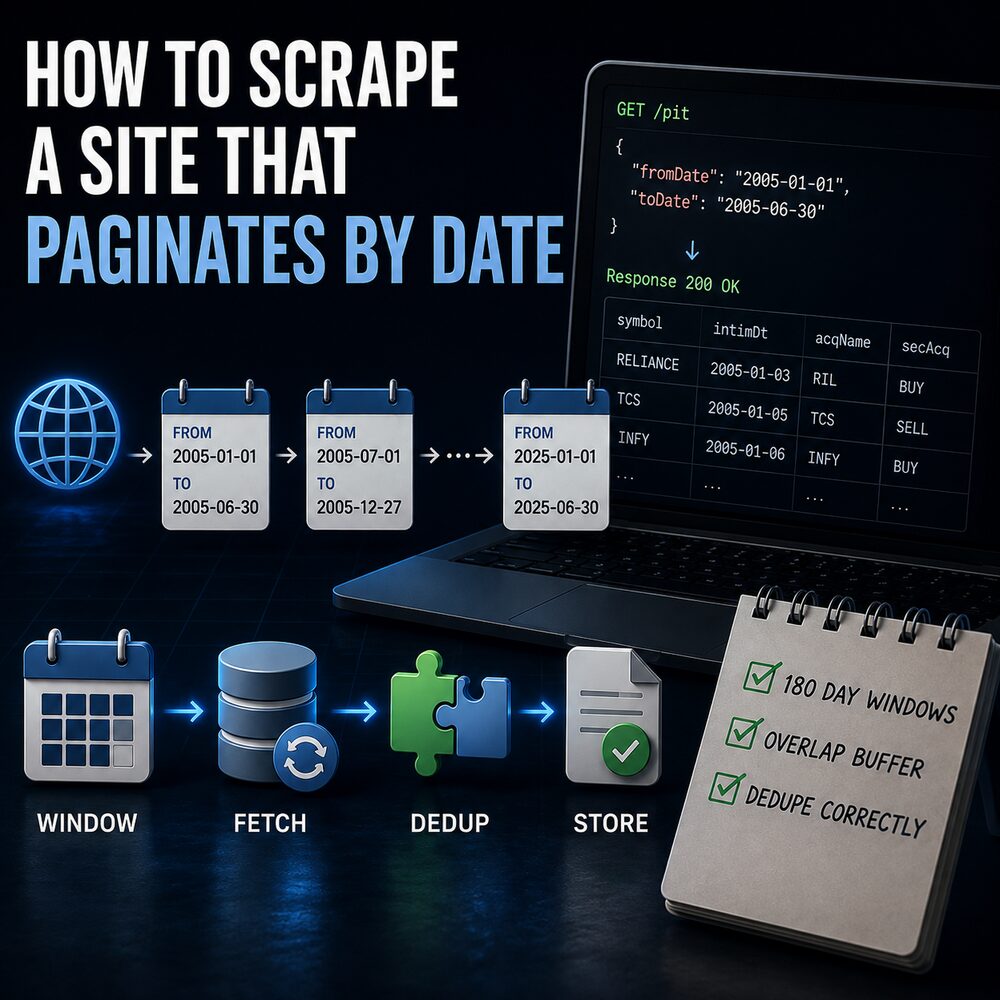
A lot of public archives use time-based pagination rather than page numbers: give me a start date and an end date, and I will give you what falls between them. Regulatory filings, press releases, court records, transaction histories. Pulling twenty years out of one is a few hundred requests, a way to remember where you stopped, and — the part that decides whether the result is any good — a way to notice when an answer came back short.
Because these endpoints do not tell you when they gave you less than you asked for. No error, no truncation flag, no total count to check against. A short response and a complete one are the same shape, and every design decision below follows from that.
Window sizing: finding the undocumented cap
The obvious first attempt is one request covering the whole range. It fails in three ways depending on how wide you go, and only one of them is obvious. A very wide range times out, which is loud and easy to handle. A merely wide range returns quickly, with a valid response, containing some of the data.
So the goal is never to ask a question big enough to get truncated.
DEFAULT_CHUNK_DAYS = 180   # max span fetched per request when looping a wide range

def fetch_range(session, from_date, to_date, chunk_days, retries=3):
    """Fetch a wide date range by splitting it into chunk_days-sized windows."""
    start = from_date
    while start <= to_date:
        end = min(start + timedelta(days=chunk_days - 1), to_date)
        ...
        start = end + timedelta(days=1)
180 days is not documented anywhere. I found it by picking a period I could verify independently, requesting it at increasing widths, and watching where the count stopped growing, then backing off from that width. That is the only method I know of for a limit nobody publishes: walk into it deliberately, while you can still tell that you have. At 180 days, twenty years is about forty requests.
Two tells are worth wiring in as alarms rather than rediscovering. A response whose row count lands on a suspiciously round number — 200, 500, 1000 — is truncated until proven otherwise. And a wider window returning fewer rows than a narrower one means you crossed a limit somewhere between them.
Resumption: the lookback buffer
The first run pulls everything. Every run after that starts from the newest record stored, minus a buffer of days.
The buffer is there because records arrive late. A transaction from last Tuesday might be disclosed next Monday. Resume exactly where you stopped and you step over it permanently, since you will never ask about that date again. Size the buffer from the source's observed lateness rather than from a round number that feels safe.
Which means overlap is now normal and every update re-reads records you already have, so the deduplication step is doing real work on every run rather than sitting there as a safety net. When it is wrong, the damage is immediate.
The other half of resumption is knowing which windows you actually got, which I did not track for far too long. A run that dies partway, or a window that returned an error you retried past, leaves a hole that no amount of resuming from the newest record will ever fill — the watermark has moved beyond it. Logging every requested window with its outcome, then scanning that log for intervals you never successfully fetched, turns gap repair into a query rather than an archaeology exercise. It is three columns — window start, window end, outcome — and I would add it on day one now.
Deduplication keys: three silent failures
Deduplication means building a key from the fields that identify a record and discarding rows whose key you already hold. All three of the ways I got this wrong were invisible from the outside.
The first was naming columns that do not exist. I wrote the key from memory rather than from a response:
# What I used. None of these are real column names.
DEDUP_KEYS = ['personName', 'acqQty', 'securityName']

# What the endpoint actually returns.
DEDUP_KEYS = ['symbol', 'intimDt', 'acqName', 'secAcq']
Every row then produced the same empty key, so every filing for a company on a given day looked like one filing repeated, and the deduplicator kept one and dropped the rest. A company disclosing four transactions in a day was stored as one. Asserting that the key columns exist against the first response is one line and turns this into a startup failure.
The second was implementing the check as a merge, which against stored data that already contains duplicate keys produces one output row per match and inflates rather than deduplicates. The pipeline went from silently deleting records to silently inventing them. An anti-join cannot do that:
def deduplicate(new_df, existing_df):
    new_keys = _composite_key(new_df, DEDUP_KEYS)
    existing_keys = set(_composite_key(existing_df, DEDUP_KEYS))
    return new_df[(~new_keys.isin(existing_keys)).values]
The third is that the same record does not arrive the same way twice. The same quantity comes back as 629221 from one place and 629221.0 from another, the same date as 15-Jan-2026 here and 2026-01-15 there. As text those are different keys, so the record is stored twice.
for k in dedup_keys:
    if k == 'intimDt':
        col = pd.to_datetime(df[k], errors='coerce').dt.strftime('%Y-%m-%d')
    else:
        # '100', 100 and 100.0 all collapse to one key;
        # names are not numeric, so they fall back to their text form.
        numeric = pd.to_numeric(df[k], errors='coerce').astype('float64')
        col = numeric.where(numeric.notna(), df[k]).astype(str)
    parts.append(col.fillna('').astype(str))
return parts[0].str.cat(parts[1:], sep='|')
That reads like housekeeping and it is what makes the next problem solvable. It is also all a hand-rolled version of a unique constraint plus ON CONFLICT DO NOTHING, which is what I would use if the destination were a database.
Index lag: the archive behind itself
Collecting history is the easy half. The harder problem is that an archive's searchable index usually lags its own publication — here by roughly 30 to 60 days. For a twenty-year backfill that does not matter at all. For anything current it means the most recent two months are permanently incomplete and nothing in the response says so, because there is no marker for "still arriving".
Measuring the lag is worth doing before designing around it: take a record you know exists, ask the endpoint for the window containing it each week, and note the gap between its stated date and the date it became searchable.
The only real fix is a second source that publishes sooner, mapped onto the first source's field layout and merged. That merge is only safe because of the canonicalisation above — without it the same record from two sources produces two different keys, and you get a dataset duplicated everywhere the sources overlap, which is worse than having one source.
Blocks on the supplementary source
Two blocks, neither obvious from the error. The first was HTTP 405 through Cloudflare, unaffected by any header I changed, because the block was fingerprinting the TLS handshake rather than reading headers. curl_cffi opens the connection the way Chrome does and gets past it, and the four layers a block can come from are worth knowing before you spend a day on user agents like I did.
The more expensive half of that failure was the reporting. A fully blocked run finished successfully with zero new rows, which is exactly what a genuinely quiet day looks like. A pass and fail count at the end of the run is what stops those two ever looking the same again.
The second was a 200-record cap per response with nothing in the response to indicate it. Fetching one day at a time keeps every window under the cap, at the cost of more requests. One address will also not survive a full historical crawl, so that source runs through a rotating pool.
Verification against an external total
Every failure above has the same shape: the output was plausible, and nothing checked it against anything outside the pipeline.
Counting records for a handful of entities I could verify by hand, against the source's own published figures, would have caught the broken dedup key in a day rather than months. No amount of internal consistency would have, because the pipeline was perfectly consistent with itself. This is the check I would set up first on a new backfill, and it is a twenty-line script.
"Nothing new" needs to be treated as a claim requiring evidence — it was the visible symptom of both the block and the row cap. And it is worth deciding explicitly what happens when a record is amended after publication, because the anti-join sees a key it already holds and drops the correction. That is a side effect of set membership rather than a decision, and for a filings dataset it is the gap that bothers me most. Versioning the record instead of overwriting it, the way a dbt snapshot does, is the answer I would reach for now.
References and further reading
SEBI's Prohibition of Insider Trading Regulations, 2015 (the original gazette notification, amended several times since) set out who has to disclose what and by when. Those deadlines are the reason the data arrives late rather than wrong, and reading them is what turned "the source is unreliable" into a schedule I could design around.
NSE's insider trading disclosures page shows the same records a human would see. It is the fastest way to check a single company by hand when you suspect your own pipeline is dropping rows — and doing that check is what surfaced the deduplication bug.
The techniques, generalised
- Airflow DAG runs and backfills — the standard vocabulary for "process this window, then that one, and let a rerun repair a window that failed". Worth reading even if you never install it, because it names what a hand-rolled windowed backfill is doing.
- dbt snapshots — the standard answer to a source that revises history, which is what a filing amended after publication is.
- pandas
merge—validate="one_to_one"raises on the join that turns deduplication into duplication. - Postgres
ON CONFLICT— the deduplication problem solved by a unique constraint instead of by application code, which is what I would reach for building this again. - curl_cffi — the fix for the supplement source's TLS-level block, in one import.
- Python robotparser and RFC 9309 — what a crawler is expected to respect, in three lines of code and one short standard.
Related posts
- Why your scraper gets blocked — the four things that refuse a scraper (headers, TLS fingerprint, IP address, behaviour) and what fixes each.
- How to make an ETL pipeline safe to rerun — how to make a long backfill safe to interrupt and rerun.
- Common data ingestion bugs — a year of real pipeline failures sorted by cause, including the ones a job like this produces.
- Playwright vs Selenium — when a scrape needs a real browser and when a plain HTTP request is enough.
My own projects
- Market data platform — the platform this dataset feeds.